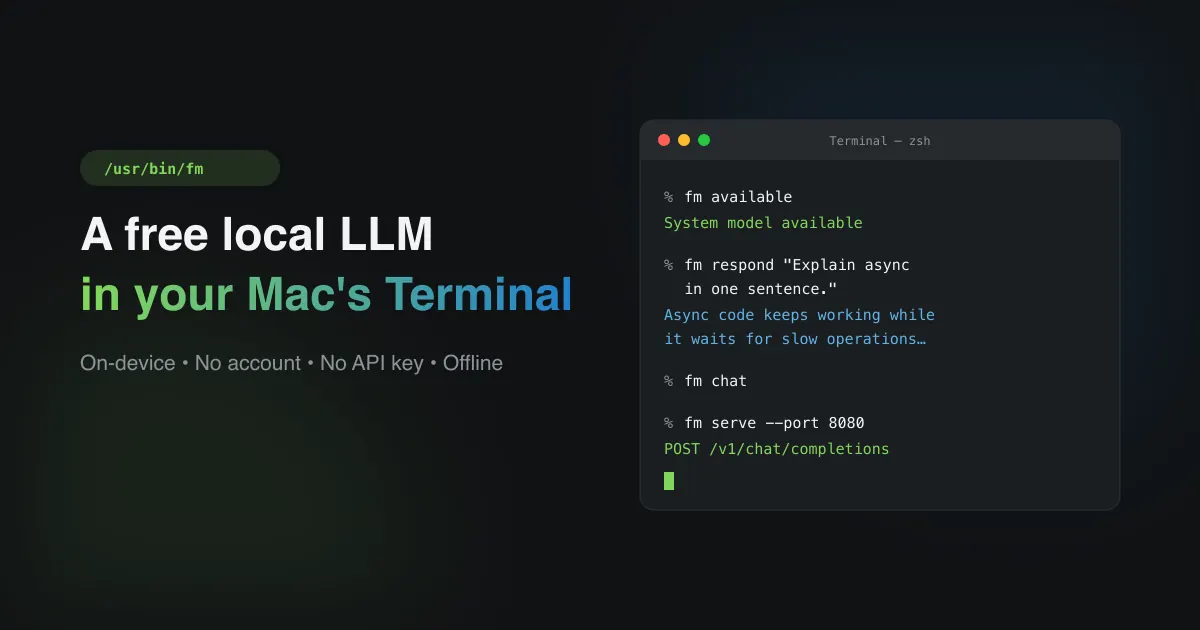
Apple’s Free Local LLM Is Hiding in macOS Terminal
There's a working local AI model in your Mac's terminal that most people never notice — free, private, and requiring no account or API key.
llmlocal-llmon-device-ai
LLM security, production ML, and AI risk — the technical side of artificial intelligence.
There's a working local AI model in your Mac's terminal that most people never notice — free, private, and requiring no account or API key.
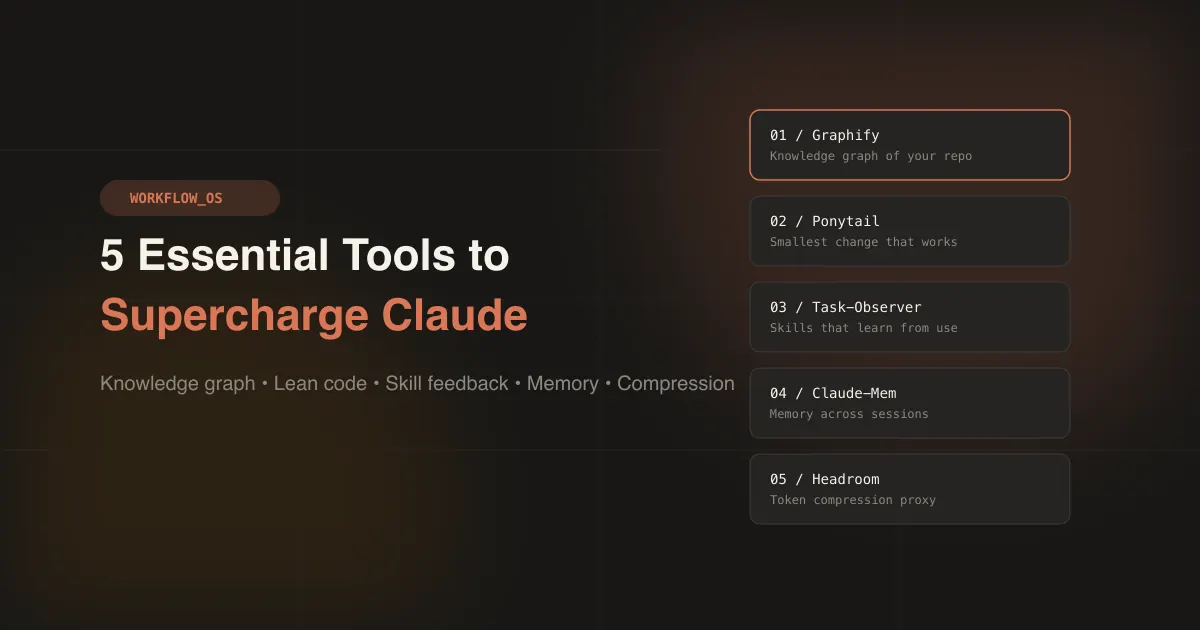
Five open-source tools—Graphify, Ponytail, Task-Observer, Claude-Mem and Headroom—that save tokens, keep context and make Claude Code more reliable.
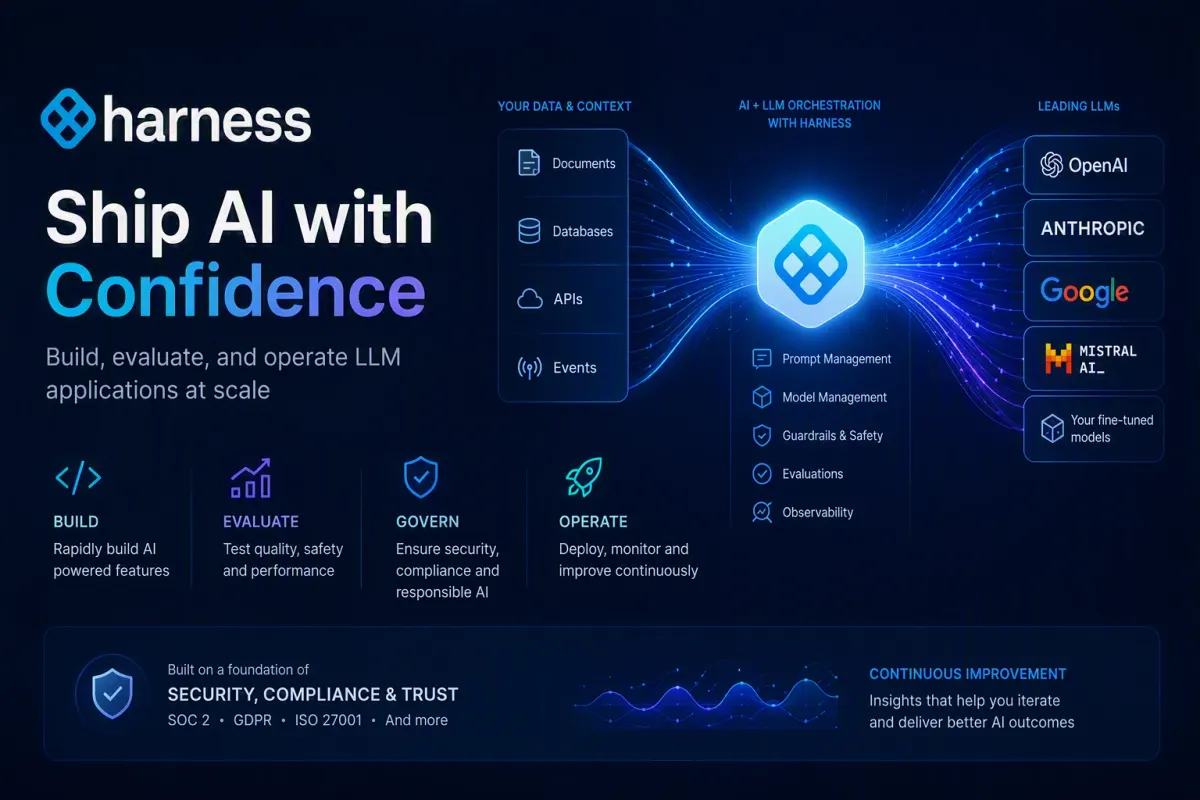
The loop makes an LLM behave like an agent, but the harness is what makes it survivable in production — tool registry, context manager, state store, guardrails, and evaluators around the model.
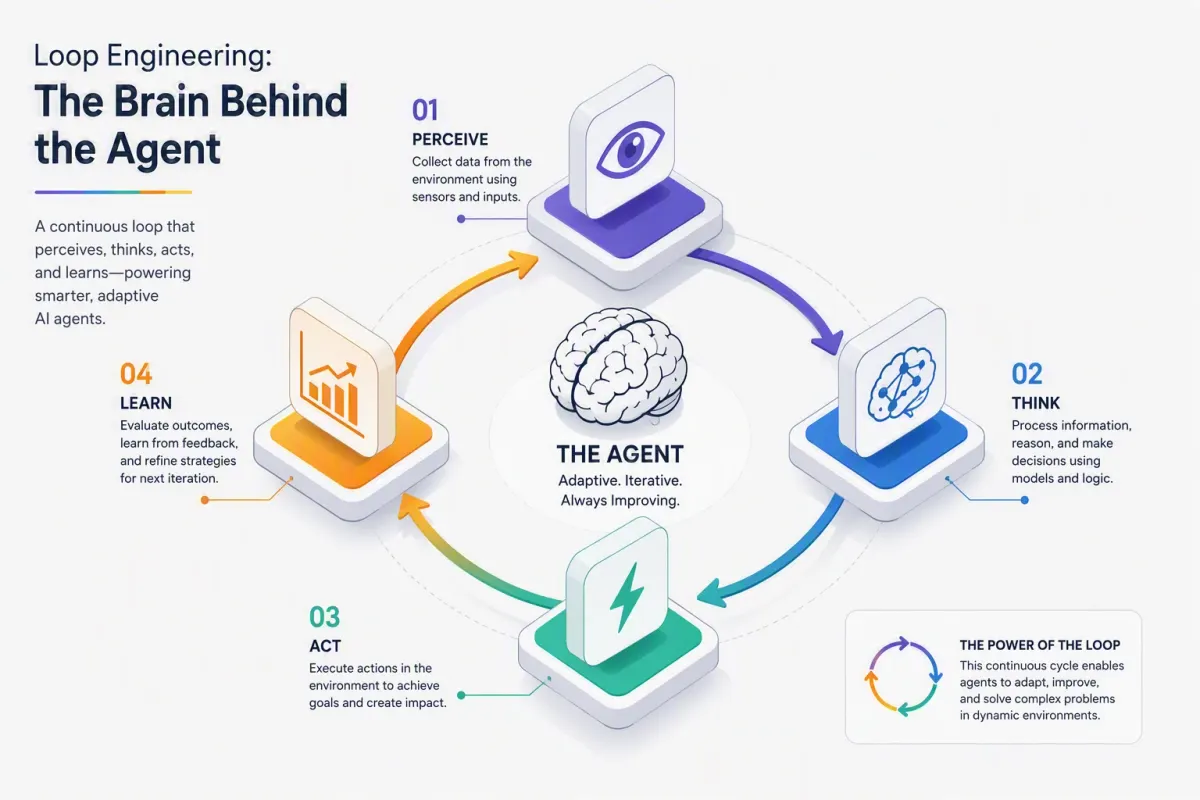
An LLM is a stateless next-token predictor. The 'brain' of an AI agent isn't the model — it's the loop you build around it. What actually happens in one iteration, and where the loop breaks in production.
The shift from giant generalists to tiny specialists. Why INT8/INT4 quantized small language models — not ever-larger frontier LLMs — are where most real business value will actually be captured.
The core plumbing behind every large language model — tokens, tokenisation, embeddings, vocabulary, and context windows — explained in plain English with examples you can actually try.
Why LLMs forget, how much they can actually remember, and the four techniques — bigger windows, RAG, persistent memory, and efficient attention — that push past the limit.
Fine-tuning bakes knowledge into the model's weights; RAG lets it look things up. A clear-eyed comparison across cost, latency, freshness, and accuracy — plus when to use both.
Fine-tune an open-source LLM on a MacBook in under ten minutes. A working LoRA + Phi-2 pipeline on Apple Silicon, trained on the GDPR, with no cloud bill attached.
Shipping an LLM behind a REST endpoint feels routine — until you realise the model itself is an attack surface. Prompt injection, exfiltration through retrieval, and timing side-channels, with fixes that actually hold up.
A ten-document RAG demo is an afternoon project. A half-million-document RAG system with real users is an engineering discipline. Here's what actually breaks, and the architecture that holds up.
11 posts